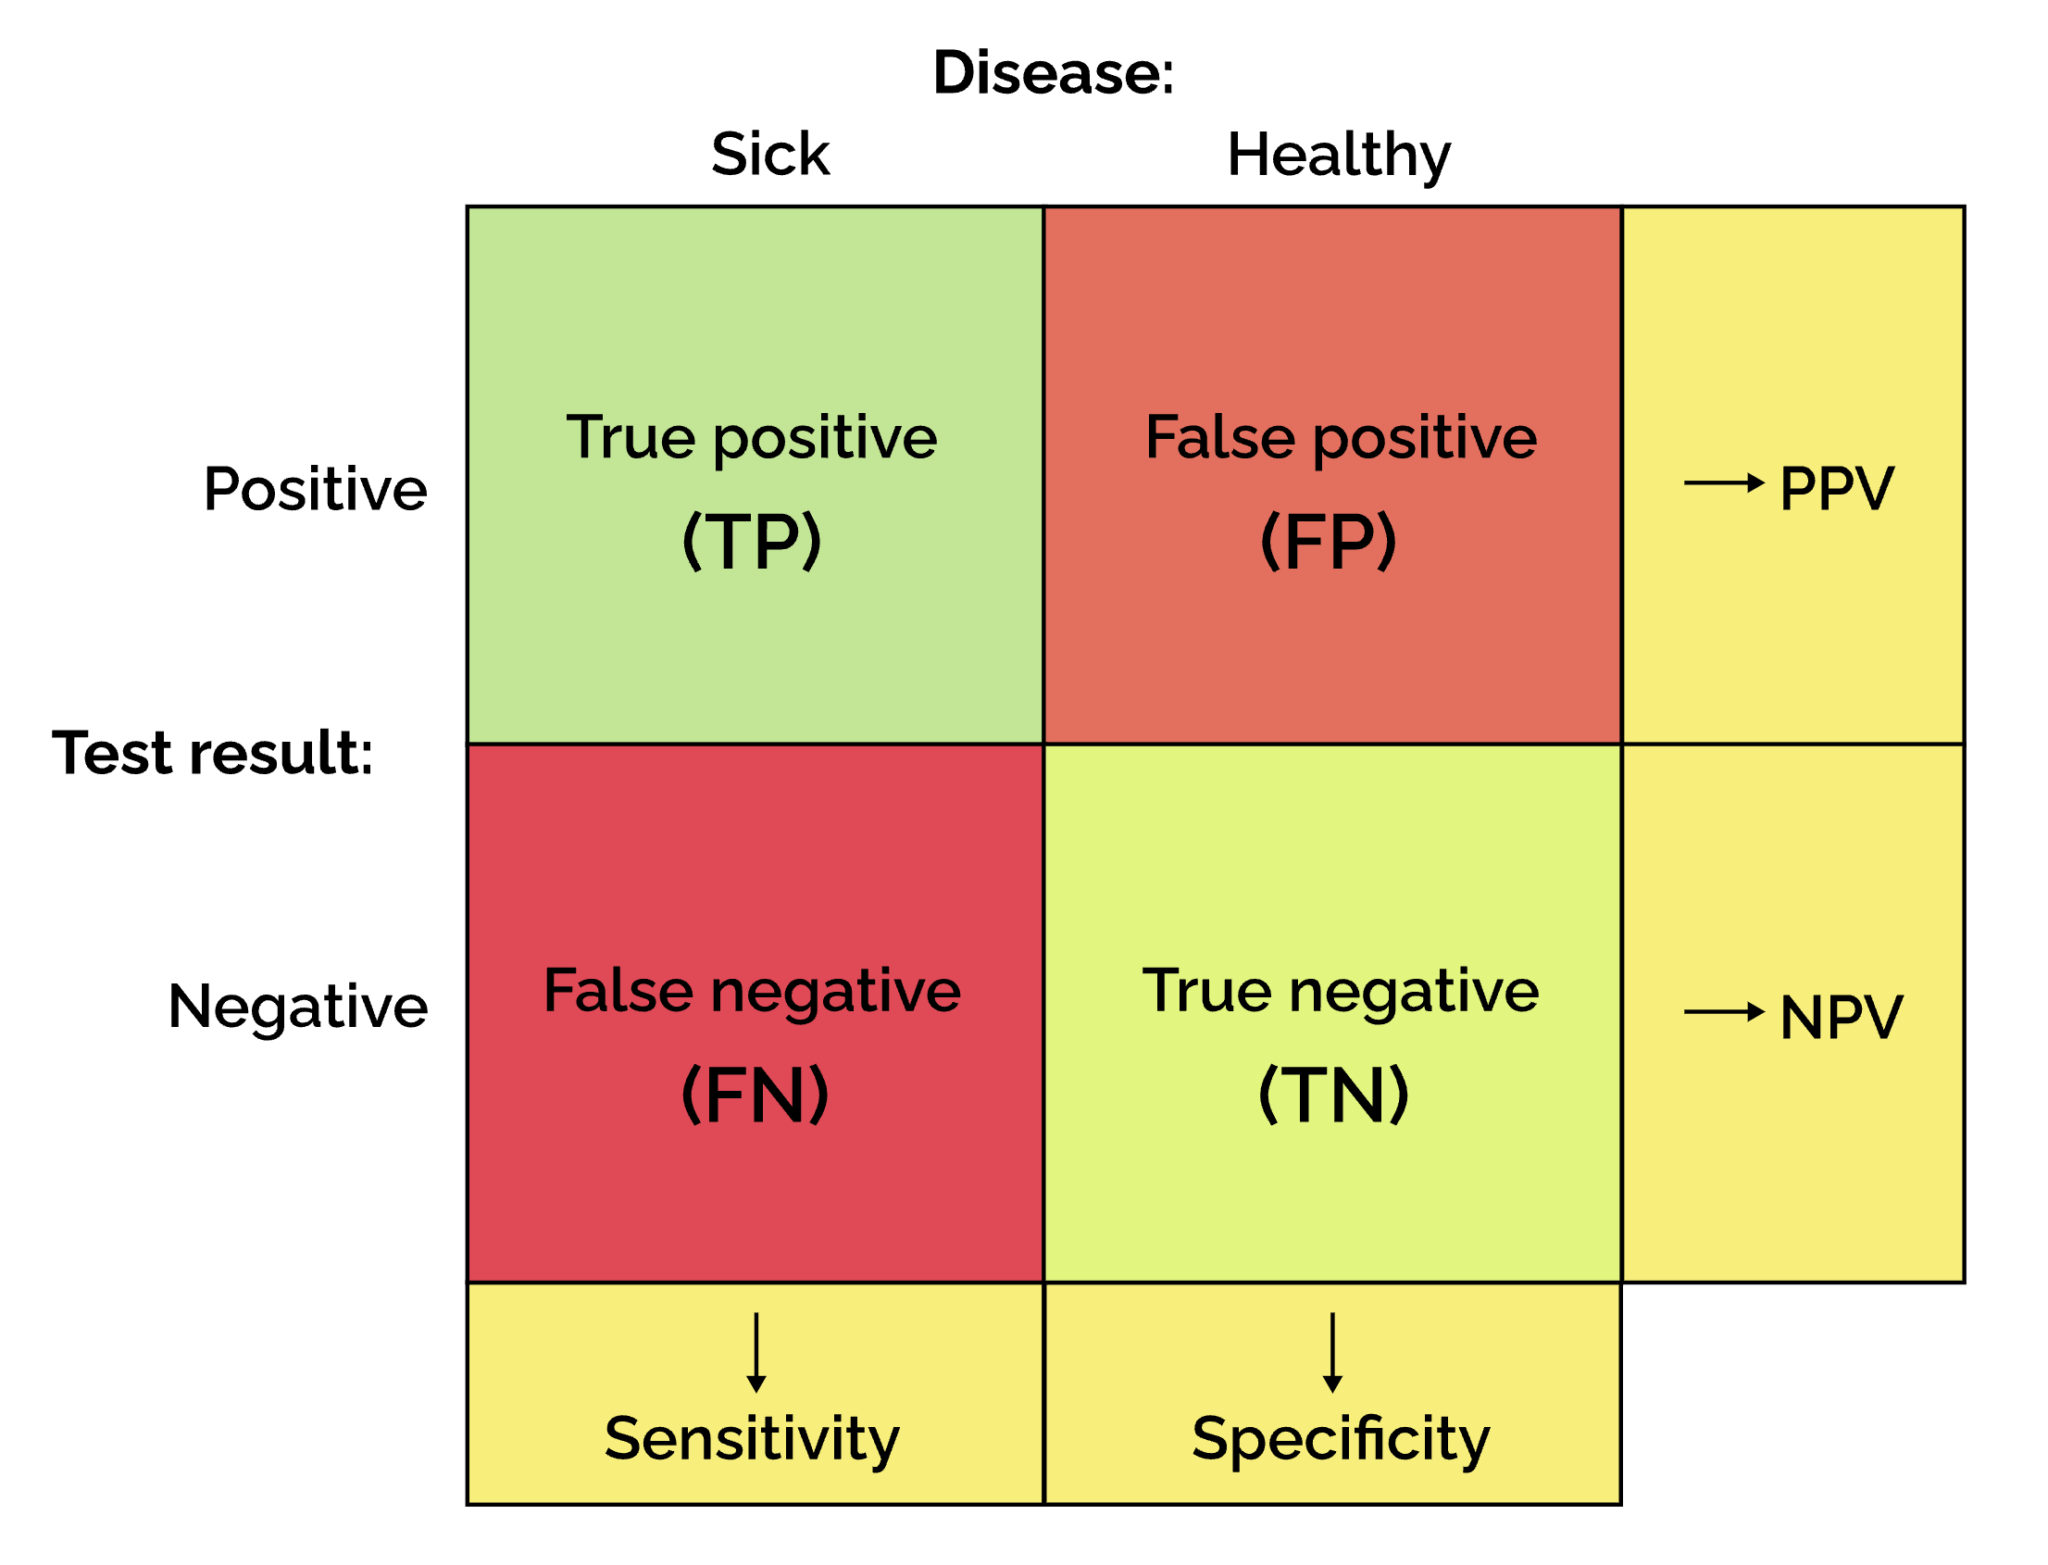

When you're trying to evaluate the performance of a diagnostic test or a machine learning model, you'll quickly realize that not all metrics are created equal. In my experience, one of the most powerful tools for understanding the trade-offs between different models or tests is the Specificity Sensitivity Table, often referred to as the confusion matrix in machine learning contexts. This table provides a clear breakdown of true positives, true negatives, false positives, and false negatives, allowing you to assess both the specificity and sensitivity of your model. Here’s the thing: while these terms might sound technical, they’re actually quite straightforward once you understand their practical implications.
What is a Specificity Sensitivity Table?
A Specificity Sensitivity Table is essentially a 2x2 grid that organizes the outcomes of a binary classification task. It’s a way to visualize how well your model or test can distinguish between positive and negative cases. The table typically looks like this:
| Predicted Positive | Predicted Negative | |
|---|---|---|
| Actual Positive | True Positive (TP) | False Negative (FN) |
| Actual Negative | False Positive (FP) | True Negative (TN) |
From this table, you can derive key metrics like sensitivity (also known as recall or true positive rate) and specificity (true negative rate). Sensitivity measures the proportion of actual positives correctly identified, while specificity measures the proportion of actual negatives correctly identified. These metrics are crucial because they highlight different aspects of your model’s performance, depending on what you prioritize.
Why Specificity and Sensitivity Matter
In my work, I’ve found that the choice between optimizing for specificity or sensitivity often depends on the context. For example, in medical diagnostics, a false negative (missing a disease) can be far more costly than a false positive (incorrectly diagnosing someone). In this case, you’d prioritize sensitivity. Conversely, in fraud detection, a false positive (flagging a legitimate transaction as fraudulent) might be more problematic than a false negative (missing actual fraud), so you’d focus on specificity. This is where the Specificity Sensitivity Table becomes invaluable—it allows you to see these trade-offs clearly.
How to Interpret the Table
Interpreting the Specificity Sensitivity Table requires understanding the relationships between its components. Here’s a breakdown:
- Sensitivity (Recall): TP / (TP + FN)
- Specificity: TN / (TN + FP)
- Precision: TP / (TP + FP)
- Accuracy: (TP + TN) / Total
Honestly, the most common mistake I see is confusing sensitivity and specificity. Remember: sensitivity is about catching all the positives, while specificity is about correctly identifying negatives. When I tested models in a recent project, I noticed that a high sensitivity often came at the cost of lower specificity, and vice versa. This is where it gets interesting—you can’t always have both, and the Specificity Sensitivity Table helps you decide which metric to prioritize.
Practical Applications
Let’s say you’re developing a model to predict customer churn. You might start by focusing on sensitivity to catch as many at-risk customers as possible. However, if your model flags too many false positives, it could overwhelm your customer service team. This is where the table helps you strike a balance. In my experience, iterating on the model while constantly referring to the Specificity Sensitivity Table ensures that you’re making informed decisions.
💡 Note: Always consider the business impact of false positives and false negatives when interpreting the table. What’s acceptable in one context might be disastrous in another.
Common Misconceptions
One misconception I often encounter is that a model with high accuracy is always the best choice. That’s not necessarily true. For instance, if your dataset is imbalanced (e.g., 95% negatives and 5% positives), a model that predicts everything as negative could achieve 95% accuracy but be useless in practice. This is why sensitivity and specificity are more reliable metrics in such cases. The Specificity Sensitivity Table forces you to look beyond surface-level accuracy and understand the nuances of your model’s performance.
Tools and Techniques
There are several tools and libraries that make it easy to generate and analyze Specificity Sensitivity Tables. In Python, for example, the sklearn.metrics.confusion_matrix function is a go-to. When I tested this function, I found it incredibly useful for quickly visualizing model performance. Pairing it with classification_report gives you a comprehensive view of precision, recall, and F1-score, which are derived from the same underlying data.
⚠️ Note: Be cautious when using pre-built functions—always double-check that the output aligns with your specific use case. Misinterpreting the table can lead to flawed conclusions.
In the end, the Specificity Sensitivity Table is more than just a grid of numbers—it’s a lens through which you can critically evaluate your model’s performance. By understanding its components and implications, you’ll be better equipped to make informed decisions, whether you’re fine-tuning a machine learning model or assessing a diagnostic test. The key is to remember that no single metric tells the whole story. Use the table as a guide, but always consider the broader context of your problem.
Related Terms:
- Specificity Sensitivity Table for test
- Specificity Sensitivity Table for iron
- Specificity Sensitivity Table for concrete
- Specificity Sensitivity Table for excel
- specificity sensitivity definition
- Specificity Sensitivity Table for different