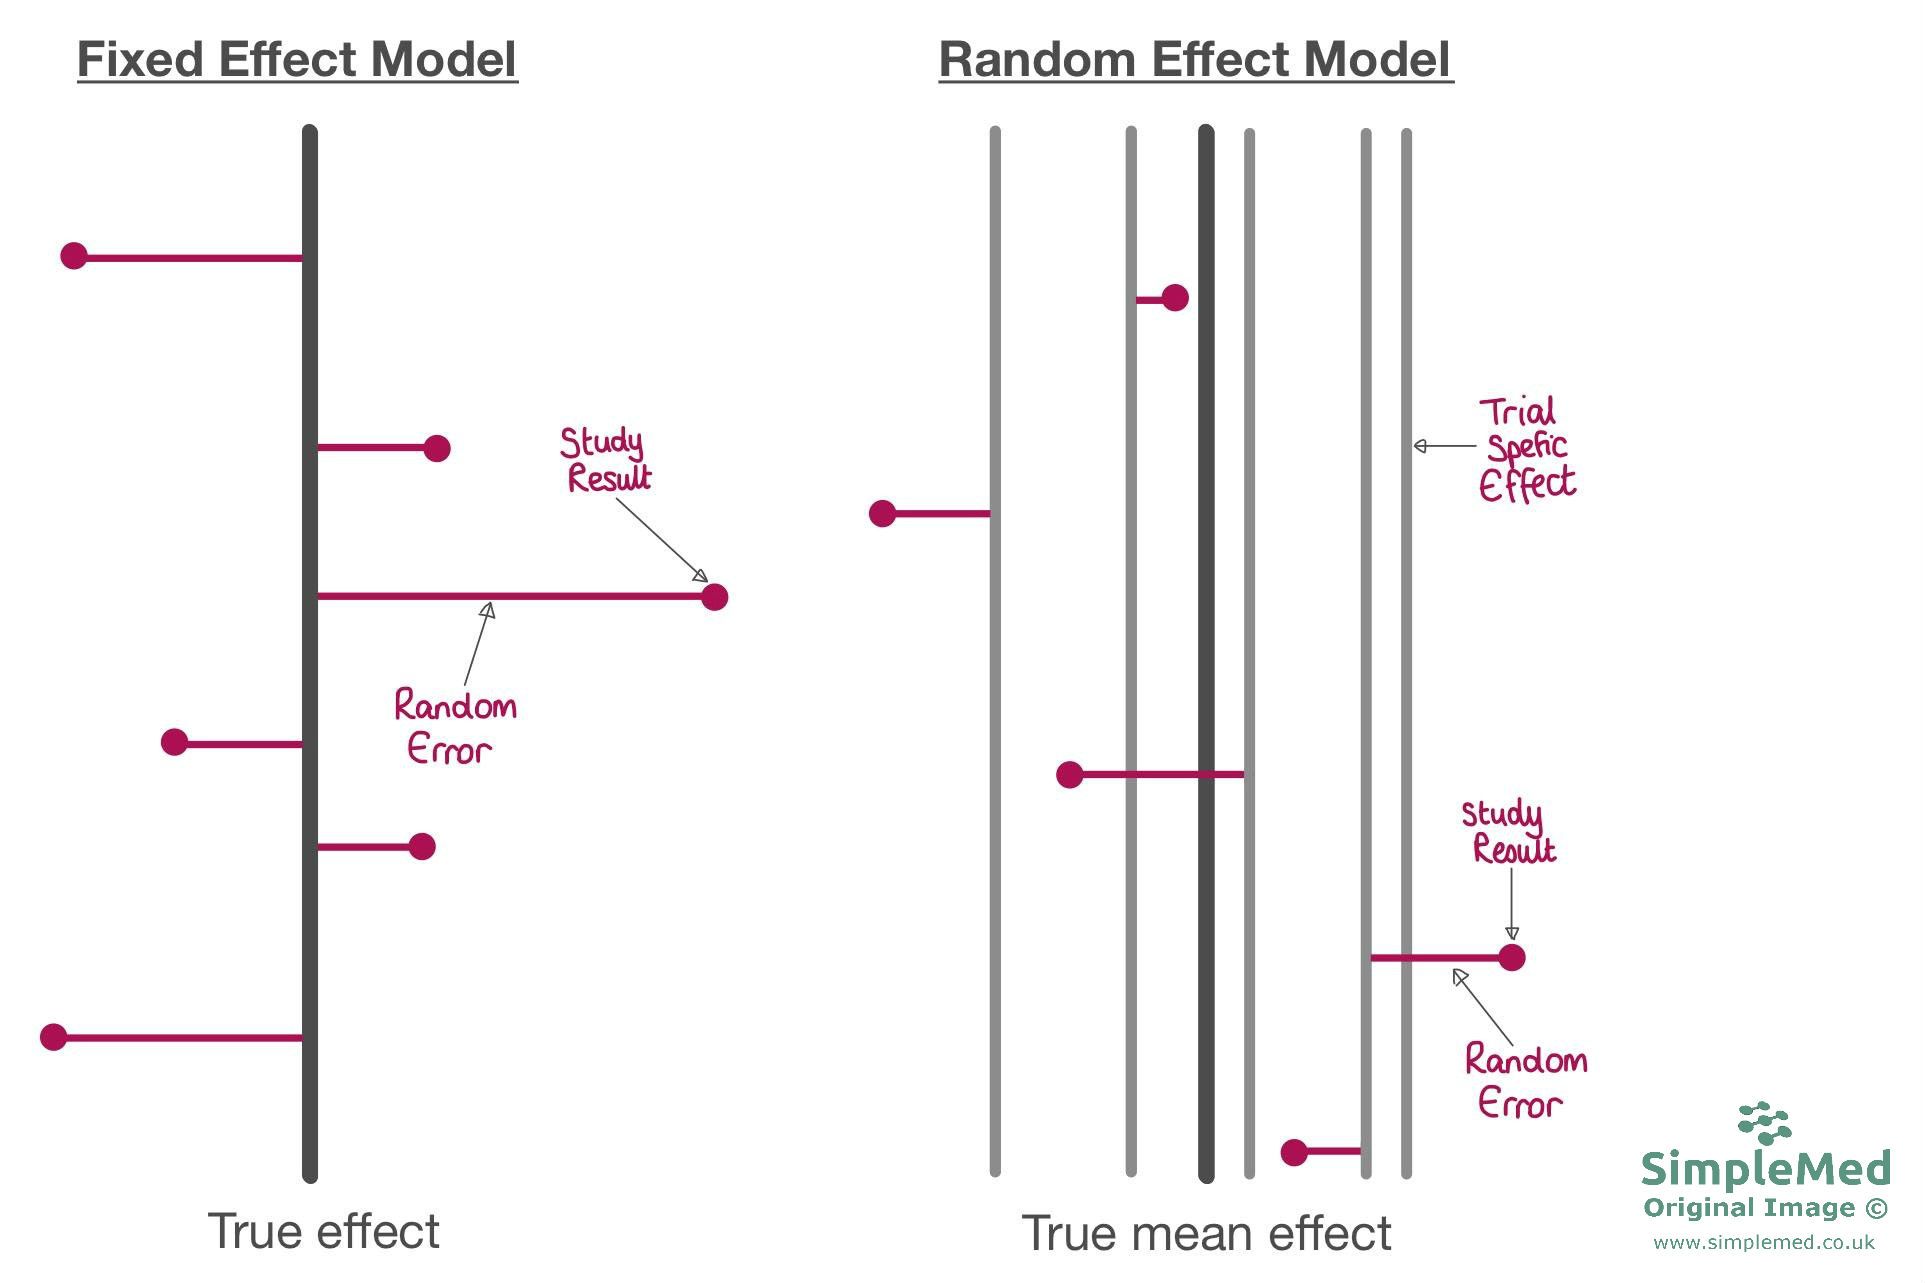

When analyzing data from experiments or observational studies, one of the first decisions you'll face is choosing between random effects versus fixed effects models. I've seen researchers and analysts struggle with this choice, often defaulting to fixed effects without fully understanding the implications. Here's the thing: the decision isn't just about statistical rigor—it directly impacts how you interpret your results. In my experience, the distinction boils down to whether you view your data as a complete population or a sample from a larger universe. This choice affects everything from the assumptions you make to the conclusions you draw.
Understanding the Core Difference
At its core, the debate of random effects versus fixed effects hinges on how you treat the variables in your model. In a fixed effects model, the levels of the variable are all the levels you care about—they’re fixed and non-random. Think of it as analyzing data from a specific set of schools to understand their performance. In contrast, a random effects model treats the levels as a random sample from a larger population, allowing you to generalize beyond the observed data. For instance, if you’re studying schools but want to infer something about all schools nationwide, random effects might be more appropriate.
When to Use Fixed Effects
Fixed effects models are powerful when your focus is on the specific entities in your dataset. I’ve found them particularly useful in panel data, where you’re tracking the same subjects over time. For example, if you’re analyzing how changes in policy affect GDP across specific countries, fixed effects can control for unobserved time-invariant characteristics unique to each country. However, this comes at a cost: you sacrifice the ability to generalize to countries not in your dataset.
Key Advantages of Fixed Effects
- Controls for unobserved heterogeneity: Fixed effects can account for variables that don’t change over time but might affect your outcome.
- Focus on within-group variation: This model isolates changes within the same entity, making it ideal for studying dynamic effects.
When to Use Random Effects
Random effects models shine when you’re interested in making broader inferences. If you’re studying patient outcomes in hospitals and want to understand trends across all hospitals—not just the ones in your dataset—random effects allow you to generalize. This model assumes that the effects of your variables are drawn from a larger distribution, which is particularly useful when your data is a sample of a larger population.
Key Advantages of Random Effects
- Efficiency in estimating coefficients: Random effects can provide more precise estimates when the assumptions hold.
- Ability to generalize: This model allows you to make inferences about the population beyond your observed data.
Comparing Random Effects Versus Fixed Effects
| Aspect | Fixed Effects | Random Effects |
|---|---|---|
| Treatment of Variables | Fixed, non-random levels | Random sample from a population |
| Generalizability | Limited to observed data | Allows broader inferences |
| Assumptions | No correlation between variables and error term | Effects are uncorrelated with predictors |
| Computational Complexity | Higher, especially with large datasets | Generally less complex |
Practical Considerations
Choosing between random effects versus fixed effects isn’t always straightforward. I’ve seen analysts default to fixed effects because it feels more conservative, but this can lead to overfitting if the data doesn’t warrant it. Conversely, assuming random effects without justification can yield biased estimates. Here’s a practical tip: always test your assumptions. Tools like the Hausman test can help you decide, but remember, no test is foolproof. Context matters.
⚠️ Note: The Hausman test is a common diagnostic tool, but it relies on specific assumptions. Don’t use it blindly—consider the theoretical underpinnings of your model first.
Real-World Applications
In my work with longitudinal data, I’ve found that fixed effects often provide clearer insights into causal relationships within specific groups. For instance, when analyzing employee productivity across departments, fixed effects helped isolate the impact of managerial changes. On the other hand, random effects were more suitable when studying patient recovery rates across hospitals, as the goal was to understand trends in healthcare systems broadly.
That said, the choice isn’t always binary. Mixed models, which combine elements of both, can be a middle ground. Honestly, the best approach depends on your research question and data structure. Don’t force a model to fit—let the data and theory guide your decision.
In the end, understanding random effects versus fixed effects is about more than statistical correctness—it’s about aligning your methodology with your goals. Whether you’re analyzing policy impacts, clinical trials, or market trends, the right model ensures your findings are both accurate and meaningful. So, next time you’re faced with this choice, take a step back, consider your data, and ask: What story am I trying to tell? The answer will point you in the right direction.